


Executive Summary
Bayleys Real Estate is one of New Zealand’s largest full-service real estate companies, operating across commercial, industrial, residential and rural property. Its valuers rely on an internal Commercial Valuation Evidence (CVE) application to record, search and report on the sales and rental evidence behind every commercial valuation.
Bayleys partnered with Peritos Solutions to replace the ageing Access-based system with a modern platform that valuers could use from any device. Peritos designed and delivered a fully serverless AWS application in under two months. Valuers can now search evidence on a map, attach photos and documents, and export reports to Word, Excel and PDF, all through their existing Bayleys login.
“The team was quick to respond, very cooperative, and genuinely focused on delivering quality results.”
Biswa Mishra, Director, Wizmonk (Peritos AWS client)
Project outcomes
Results & Impact
Background
The CVE application had run on a Microsoft Access database for many years. It was a standalone, desktop-bound tool with no cloud access, no modern search and no ability to scale with a growing team of valuers.
Bayleys needed the application moved to a cloud-native platform that could be accessed from anywhere, aligned with its existing Azure AD identity and roles, and gave valuers a much better experience for entering and finding property evidence.

Challenge
Moving years of property data to the cloud was far more than a lift-and-shift. The Access database had an unstructured schema built through years of ad hoc data entry. It had to be remapped, converted and validated record by record before go-live.
Bayleys staff needed to sign in with their corporate Azure AD accounts, which meant integrating Microsoft identity with an AWS-native application. The new platform also had to handle specialist valuation fields such as yield, IRR and WALT exactly as valuers expect, and restrict all address searches to New Zealand. All of this had to be delivered in under two months.
Solution
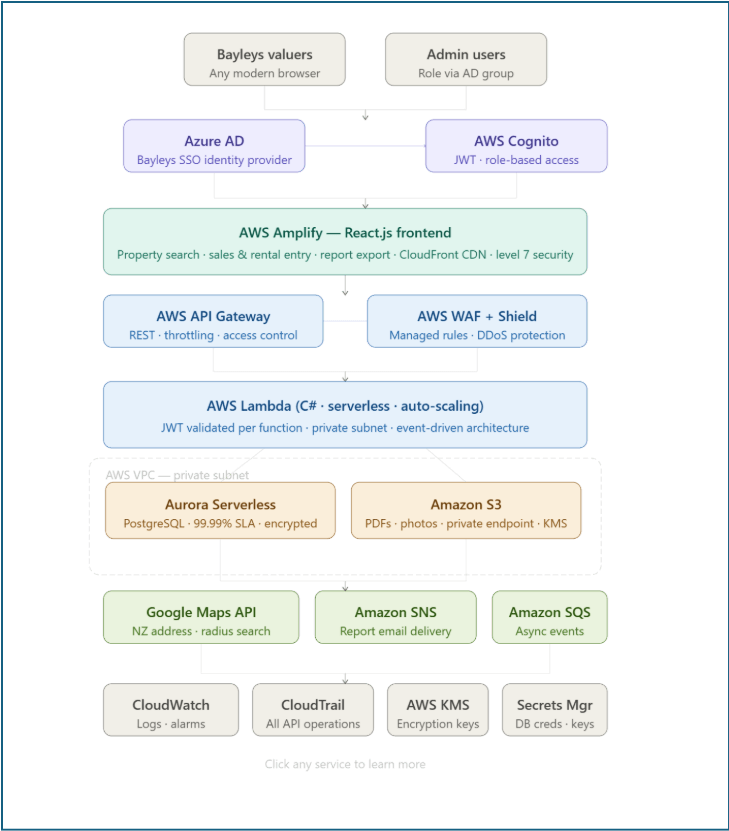
Peritos built a fully serverless platform on AWS, following the AWS Well-Architected Framework. The application uses a React.js frontend on AWS Amplify, C# APIs on AWS Lambda and an Amazon Aurora PostgreSQL database. There are no servers to manage, the platform scales automatically, and Bayleys pays only for what it uses. The total running cost is around USD $124 a month.
Staff sign in through AWS Cognito connected to Bayleys’ Azure AD, with admin rights managed through existing Microsoft groups. Valuers can search evidence by property type, price, area, tenure or keyword, and use Google Maps radius search to find comparable evidence near any NZ address. The platform is secured with AWS WAF, Shield, KMS encryption and Secrets Manager, and every data export is captured in an audit log.
Inside the application
-
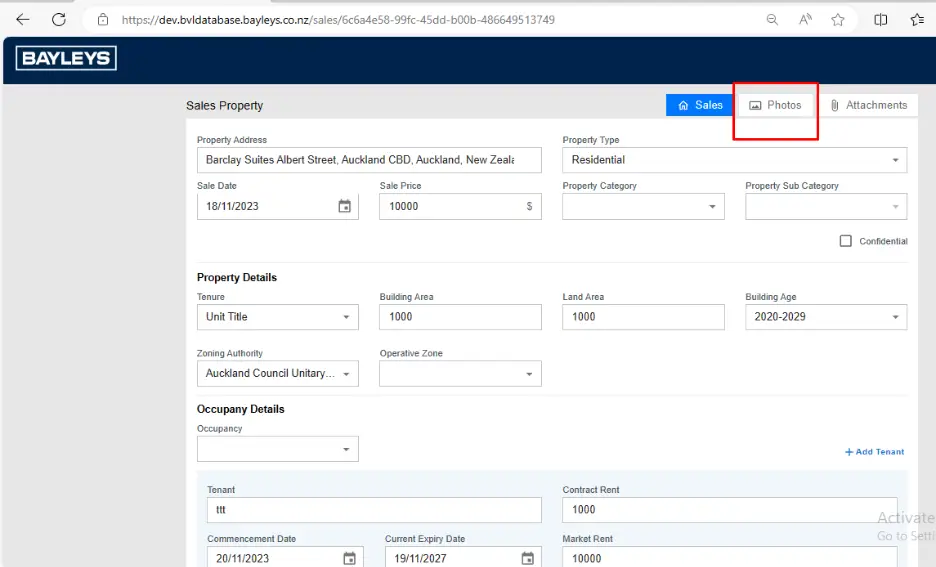
- Property evidence search with map radius
-
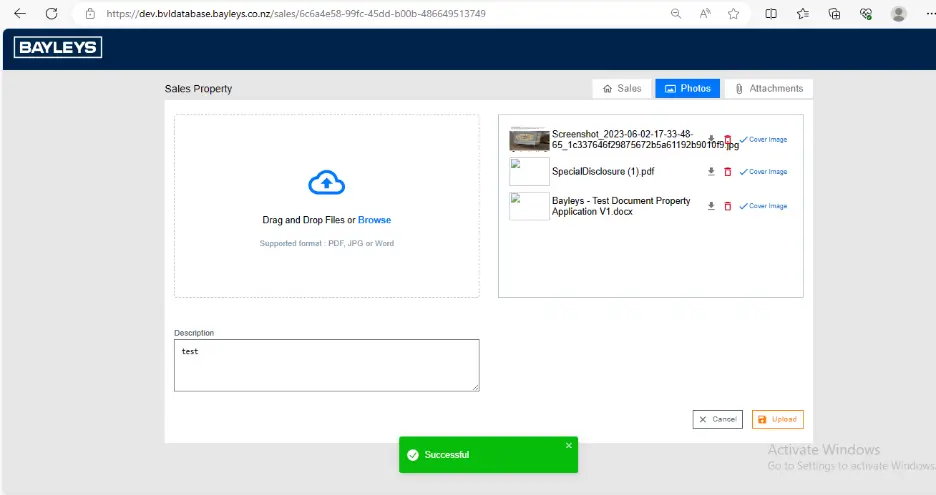
- Sales and rental evidence entry
-
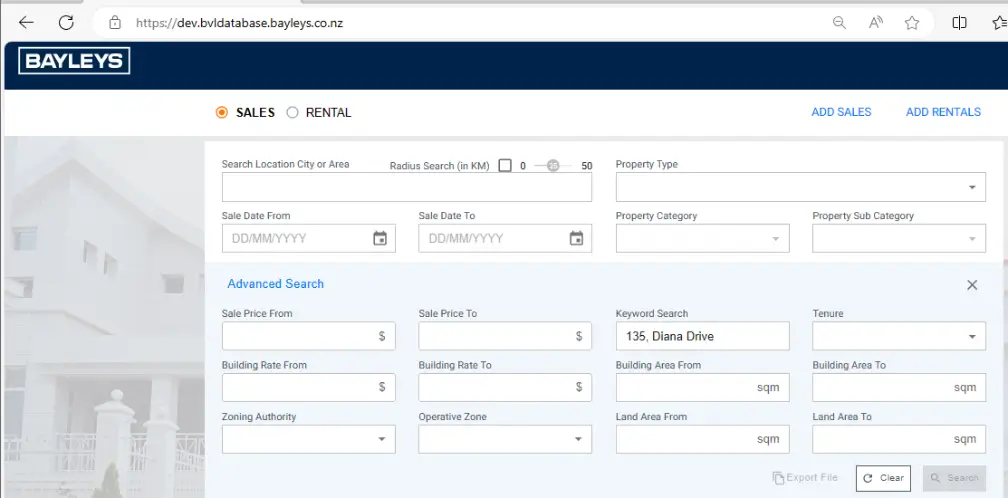
- Evidence reports and export
Approach
Peritos began with a structured assessment before any build started. The team reviewed the existing database, designed the target cloud architecture, completed a Well-Architected review across all five pillars, and validated AWS costs upfront.
Delivery then ran as parallel workstreams across infrastructure, backend, frontend and data migration, with daily sprints and fast feedback from Bayleys valuers. The core application was built first, followed by exports, map search and audit logging. Data migration, user testing and go-live came last. All 45+ test cases passed with only three bugs raised, and a month of free hypercare followed launch before Bayleys moved to ongoing support.
“Peritos are very easy to work with and have excellent development skill. They were dedicated and committed to our project and provided great service.”
John Leeves, Director, Tonkin + Taylor (Peritos AWS client
About the Client
| Client | Bayleys Real Estate |
| Industry | Commercial & residential property | sales · valuation · property management |
| Region | New Zealand | one of NZ’s largest full-service real estate companies |
| Application | CVE — Commercial Valuation Evidence | internal property evidence platform |
| Legacy | Microsoft Access database → migrated to Aurora PostgreSQL on AWS |
| Delivered by | Peritos Solutions | Oct 2023 – Dec 2023 |
Bayleys is one of New Zealand’s leading full-service real estate companies, operating across commercial, industrial, residential and rural property. Their internal CVE application is used by valuers to record, search, and report on commercial sales and rental evidence across the New Zealand market.
Project Background
Bayleys’ existing Commercial Valuation Evidence system ran on a legacy Microsoft Access database — a standalone, desktop-bound solution with no cloud access, no modern search capability, and no ability to scale to a growing user base. The requirement was to migrate the entire application to a cloud-native platform that could be accessed from any device, support role-based access aligned to Bayleys’ existing Azure AD identity, and provide a significantly improved user experience for valuers entering and searching property evidence.
Peritos Solutions was engaged to design, build, and deploy the full application on AWS — from architecture design and Access database migration through to a React.js frontend, serverless C# API layer, Aurora PostgreSQL database, and production deployment — in under two months.
Project Timelines
| Phase | Period | Key Activities | Status |
| Phase A | Oct 2023 | Requirement gathering, AS IS / TO BE flows, business architecture, application design, AWS account structure setup (Dev/Test/Prod OUs) | Done |
| Phase B | Oct – Nov 2023 | AWS infrastructure setup, React.js frontend, C# Lambda APIs, AWS Cognito + Azure AD SSO, property search, sales entry, rental entry, photo/attachment upload, CI/CD pipelines, unit testing | Done |
| Phase C | Nov – Dec 2023 | Word/Excel export, Google Maps radius search, audit logs, email report delivery, advanced search enhancements | Done |
| Phase D | Dec 2023 | Access DB data migration to Aurora PostgreSQL, UAT, bug fixing, production deployment, documentation & handover | Done |
| Hypercare | Dec 2023 | 1-month free hypercare post go-live, then transition to support contract | Done |
Results & Impact
Observability & Visibility
Assessment Report
Phase A delivered a structured assessment before any build commenced:
- Risk & Gap Analysis — AS IS Access database reviewed, TO BE cloud architecture designed, data migration approach confirmed, and AWS account structure (Dev/Test/Prod organisation units) set up before development started
- Customised Assessment Report — AWS Well Architected Framework assessment completed across all five pillars (Operational Excellence, Security, Reliability, Performance Efficiency, Cost Optimisation), with adherence built into the architecture from day one
- Pricing validated — full AWS pricing model confirmed at USD $124.22/month (Asia Pacific Sydney) before infrastructure was provisioned
Cloud Formation
Serverless AWS Architecture
The entire application was built on a consumption-based serverless model:
- AWS Lambda (C#) — all backend APIs run serverless with automatic scaling, zero server management, and 99.95% SLA
- Aurora Serverless PostgreSQL — database scales automatically with demand, 99.99% SLA, deployed in a private subnet with no public internet access
- AWS Amplify — React.js frontend deployed on a managed CloudFront distribution with built-in level 7 security — no additional CDN or WAF configuration required for the frontend
- CloudFormation IaC — all three environments (Dev/Test/Prod) provisioned from identical infrastructure-as-code scripts, ensuring full environment parity
Scope & Requirements
Phase A — Requirements & Architecture
- AS IS and TO BE process flows documented for sales and rental evidence workflows
- AWS account structure designed — separate Dev, Test, and Prod accounts under an Organisation Unit hierarchy
- Application architecture designed — serverless, multi-layer (Presentation · Business Services · Data Access)
- AWS Well Architected Framework review completed across all 5 pillars
- AWS pricing model confirmed — USD $124.22/month
Phase B — Core Application
- AWS infrastructure setup — VPC, private subnets, CloudFormation scripts, CI/CD pipelines
- User authentication — AWS Cognito with Azure AD as identity provider; JWT token validation on every Lambda; admin/user role assignment from AD groups
- Home screen and navigation — role-based dashboard
- Commercial Valuation Evidence (CVE) module — full sales evidence entry with NZ address restriction
- Property search — by type, category, subcategory, location, date range, price, building area, tenure, zoning, keyword
- Rental Assessment module — rental entry with auto-calculated annual rental (area × contract rate), lease terms, occupancy details
- Photo and document attachment — upload, download, and delete for both sales and rental records; stored in S3
- Sales and rental evidence report — combined report generation
- AWS deployment — Lambda, Aurora, Amplify, API Gateway, WAF, S3, KMS, Secrets Manager, CloudWatch
Phase C — Additional Features
- Word and Excel export of property evidence reports
- Google Maps radius search — restrict property search to X km radius of a searched NZ address
- Audit logs — logging of all data download and export events
- Email report delivery — send evidence reports via SNS/SQS email integration
- Advanced search enhancements — comma formatting on numeric fields, improved address suburb search
Phase D — Data Migration & Production
- Full data migration from Microsoft Access database to Aurora PostgreSQL
- UAT, bug fixing (5% effort allocation), production deployment
- Documentation and handover
- 1-month hypercare support post go-live
Implementation
Serverless Architecture
The backend was built entirely on AWS Lambda using C#, invoked via Amazon API Gateway. This eliminated server management entirely — Lambda scales automatically to handle any volume of concurrent requests, and the consumption-based pricing model means Bayleys pays only for actual usage. At 50,000 Lambda invocations per month, the Lambda cost is effectively zero under AWS’s free tier thresholds.
Authentication — Azure AD + AWS Cognito
Bayleys users authenticate using their existing Bayleys corporate Azure AD credentials. AWS Cognito is configured with Azure AD as the federated identity provider — users click ‘Sign in with Bayleys account’, are redirected to Azure AD for authentication, and returned to the CVE app with a JWT token. Admin role assignment is handled via Azure AD group membership, surfaced in the JWT claim and enforced on every Lambda endpoint.
Property Search & Google Maps Integration
The property search module allows Bayleys valuers to search commercial sales and rental evidence by property type, category, subcategory, location, date, price, building area, tenure, and keyword. NZ address lookup is powered by the Google Maps Places API with results restricted to New Zealand addresses only. The radius search feature allows valuers to find all comparable evidence within a defined kilometre radius of any NZ address — critical for commercial valuation work.
Data Model & Migration
The existing Microsoft Access database was analysed, mapped to a normalised PostgreSQL schema, and migrated to Amazon Aurora Serverless. Aurora’s serverless configuration means the database scales its capacity units automatically based on load — dropping to near-zero cost during idle periods and scaling up for peak search and reporting activity. The database is deployed in a private subnet with no public internet access; Lambda functions access it over the private network only.
Security Architecture
All API endpoints are protected by AWS WAF with AWS managed rule groups covering common web exploits, SQL injection, and bot traffic. AWS Shield Standard provides DDoS protection at the network layer. All sensitive configuration (database connection strings, API keys, third-party credentials) is stored in AWS Secrets Manager in encrypted format. Data at rest in Aurora and S3 is encrypted using AWS KMS. All data in transit is secured via HTTPS/TLS.
Technology & Architecture
| Frontend | React.js | AWS Amplify | responsive | Chrome · Edge · Firefox · Safari |
| Backend | C# (.NET) | AWS Lambda (serverless) | AWS API Gateway | event-driven architecture |
| Database | Amazon Aurora Serverless (PostgreSQL) | 99.99% SLA | auto-scaling | private subnet |
| Auth | AWS Cognito | Azure AD as identity provider | JWT tokens | role-based access (admin / user) |
| Storage | Amazon S3 | PDFs · photos · attachments | private endpoint access from Lambda | KMS encryption |
| Networking | AWS VPC | private subnets for Lambda & Aurora | AWS WAF on API Gateway | AWS Shield Standard |
| Security | AWS WAF (managed rule groups) | AWS Shield Standard | AWS KMS | AWS Secrets Manager | SSL/TLS |
| Notifications | Amazon SNS | Amazon SQS | email delivery for property reports |
| Monitoring | Amazon CloudWatch | AWS CloudTrail | alert & monitoring dashboards |
| DevOps | AWS CloudFormation (IaC) | CI/CD pipelines | Dev · Test · Prod environment parity |
| Integrations | Google Maps API (NZ address lookup · radius search) | Azure AD SSO | Word/Excel/PDF export |
| Region | Asia Pacific — Sydney | monthly AWS cost: USD $124.22 | 12-month total: USD $1,490.69 |
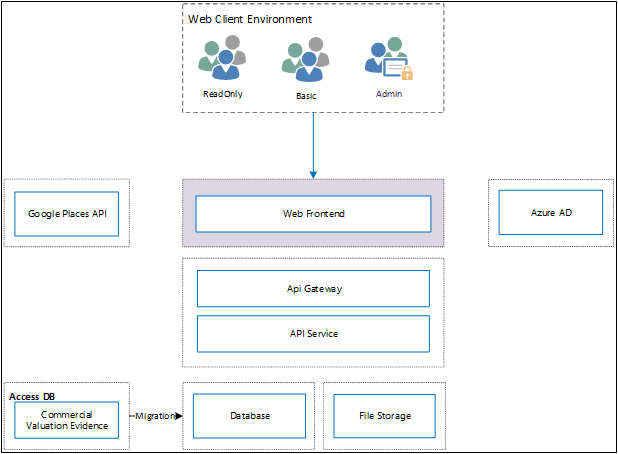
Architecture Overview
A high level architecture diagram as below
Challenges
Access Database Migration to Aurora PostgreSQL
The legacy Microsoft Access database had an unstructured schema built over many years of ad hoc property data entry. Peritos mapped the full Access data model to a normalised PostgreSQL schema before migration, handled data type conversions, and validated migrated data record-by-record against the source before go-live.
Azure AD Federated Identity via AWS Cognito
Integrating Bayleys’ corporate Azure AD as the identity provider for an AWS-native application required careful configuration of OIDC federation in Cognito, JWT claim mapping for admin role detection, and testing across all authentication edge cases — including token expiry, re-authentication, and admin privilege escalation via group membership.
NZ-Only Address Restriction
Google Maps Places API returns global results by default. Enforcing NZ-only address lookup required both frontend component configuration (restricting the Places autocomplete to NZ) and backend validation on address submission — ensuring no non-NZ property records could be created through direct API calls.
Complex Valuation Analysis Fields
The sales evidence entry form includes specialist commercial valuation fields — Building Rate ($/psm), Equivalent Market Yield (%), IRR (%), WALT (years to 2dp), Vacancy (%) — each with specific unit formatting requirements and conditional display rules (e.g. subcategory only active for Commercial Office and Commercial Retail). Getting the field logic right required close collaboration with Bayleys valuers through multiple UAT cycles.
Under Two Months End-to-End
Delivering a fully serverless custom application — including data migration, three AWS environments, CI/CD pipelines, Azure AD integration, Google Maps integration, and report export — in under two months required strict parallel workstreaming across infrastructure setup, backend development, frontend development, and data migration, with daily sprint cycles and rapid UAT feedback turnarounds.
Key Benefits
- Fully serverless — zero server management, automatic scaling, consumption-based pricing at USD $124/month for a full commercial property evidence platform
- Single sign-on — Bayleys staff use their existing corporate Azure AD credentials with no new password or account required
- Cloud-native from day one — built following the AWS Well Architected Framework across all 5 pillars, with IaC (CloudFormation) and CI/CD pipelines ensuring repeatable, reliable deployments
- Access database retired — legacy desktop-only, single-user Access database replaced by a scalable multi-user cloud application accessible from any device and browser
- Google Maps radius search — valuers can find comparable evidence within any km radius of any NZ address, directly inside the application without external tools
- 99.99% database SLA — Aurora Serverless PostgreSQL delivers enterprise-grade availability with automatic failover and no database administration overhead
- Complete audit trail — CloudWatch logging, CloudTrail, and application-level audit logs capture all data access and export activity
Post-Launch Support
Hypercare Period
A 1-month free hypercare period was included from the go-live date. Peritos monitored CloudWatch metrics, resolved all post-launch issues, and provided guidance on Aurora capacity tuning and Lambda concurrency configuration. All Phase B UAT test scenarios (45+ test cases across sales entry, rental entry, and search) were confirmed passed before the hypercare period commenced, with only 3 bugs raised and resolved during testing.
A support contract proposal was prepared for ongoing AMC support following the hypercare period, covering Lambda, Aurora, Amplify, and application-level support.
About Client
DEEPIQ simplifies industrial analytics and offers the only self-service application for end-to-end (Data + AI) OPs for the industrial world. With this app, your SMEs can digitize their expertise, and your data teams can build and deploy robust analytic pipelines.
- https://deepiq.com/
- Location: Have Offices Globally in USA, India, Canada
Project Background
DeepIQ required a proof-of-concept integration layer to extract Vendor master data and Work Order information from their SAP system and expose it to external applications. The goal was to evaluate viable integration patterns — SOAP, REST, BAPI/RFC — and deliver a working, reusable service layer that could be extended to production.
The project was executed by Peritos Solutions under a phased delivery model, beginning with an assessment and requirement-gathering sprint before moving into build and testing phases.
Scope & Requirements
In Scope
- Integration of Vendor master data (list and detail) from SAP
- Work Order data retrieval filtered by vendor number and date range
- Custom BAPI development with up to 10 input fields and up to 50 output fields
- SOAP web service (WSDL) exposure via SAP transaction SE37 / simplified web service
- REST-based service exposure via SAP SICF (z_ven_wrk_ords)
- Unit testing via SOAP UI and Postman
- JSON output serialisation using /ui2/cl_json
- 1 week of post-delivery hypercare support
Out of Scope
- Production deployment and middleware (Informatica/MuleSoft) configuration
- Customer master beyond the agreed POC scope
Project Timelines
| Phase | Duration | Key Deliverables | Status |
| Assessment | < 2 wks | Requirement gathering, SAP system access, Risk & Gap Analysis, Customised Assessment Report | Done |
| Phase B | 2–3 wks | Custom BAPI design, ABAP OOP coding, WSDL web service exposure, SOAP UI unit testing | Done |
| Phase C | 2–3 wks | REST-based SICF service (z_ven_wrk_ords), JSON output, Postman testing, 1-week support | Done |
| Hypercare | 1 wk | Post-go-live support, bug fixing, documentation handover | Done |
Results & Impact
Observability & Visibility
Assessment Report
A comprehensive assessment was completed in under two weeks. This included:
- Risk & Gap Analysis — identifying SAP version constraints, authentication settings, and BAPI structural gaps
- Customised Assessment Report — delivered to the client with architecture recommendations and approach sign-off
- Integration approach validated against SAP R/3 / S/4HANA constraints before any code was written
Cloud Formation
Integration — Delivered in < 2 Weeks per Phase
Each integration phase was scoped, built, and tested in a rapid sprint cadence:
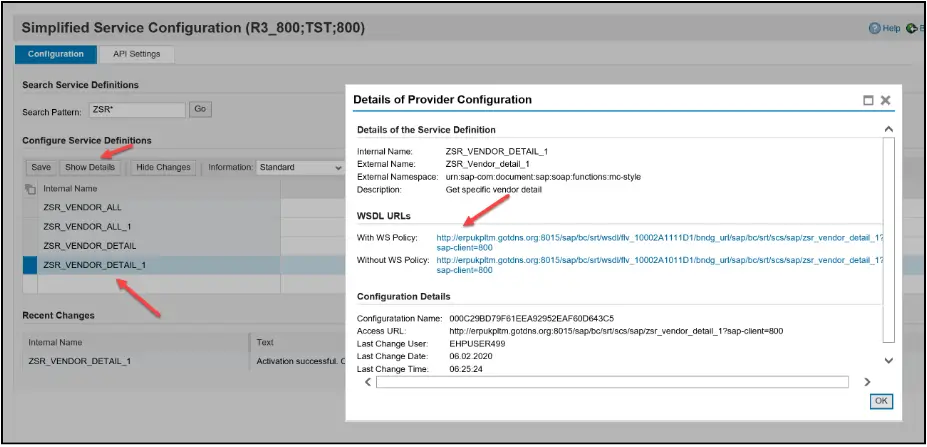
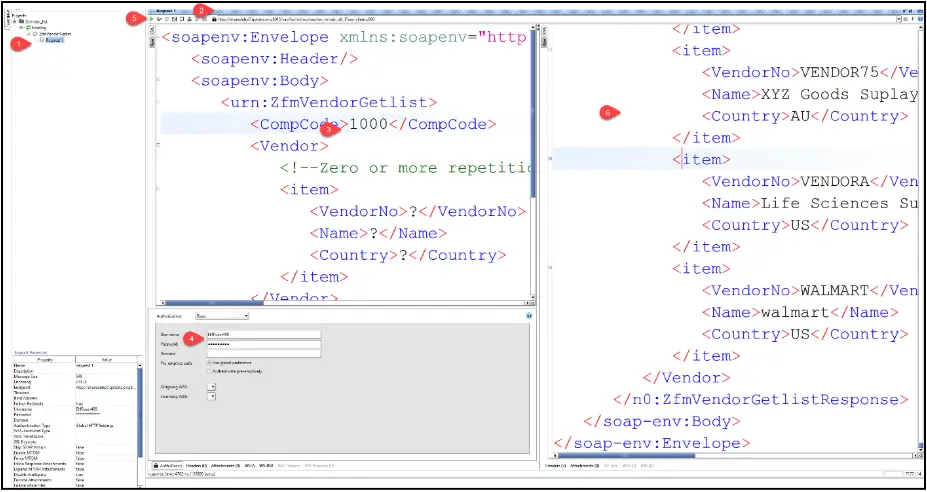
- Phase B — SOAP/WSDL: Custom BAPI (Z_VEN_WRK_ORDS) created with ABAP OOP, exposed as a simplified web service. Vendor list and detail endpoints validated via SOAP UI.
- Phase C — REST: Wrapper class implementing IF_HTTP_EXTENSION registered as a SICF service. JSON responses verified via Postman for vendor list, vendor detail, and work-order queries.
Key Outcome Metrics
| ✔ Observability & Visibility
Full assessment report delivered with risk & gap analysis within 2 weeks. |
☁ Cloud-Ready Integration
REST & SOAP web services exposed from SAP — ready for cloud consumption. |
⚡ Rapid Time-to-Value
Custom BAPI developed & tested end-to-end in under 8 weeks. |
Implementation
Architecture Overview
Below is a high level Architecture Diagram overview
Technology & Architecture
| SAP Core | SAP R/3 · S/4HANA | ABAP OOP | BAPI / RFC |
| Integration | SOAP Web Services (WSDL) | REST / HTTP (SICF) | JSON |
| Tooling | SOAP UI | Postman | Informatica ETL |
| Data Scope | Vendor Master | Customer Master | Work Orders |
| Auth | HTTP Basic Auth | Service User credentials |
| Output Format | JSON (serialised via /ui2/cl_json) | XML / WSDL |
Challenges
Authentication Configuration
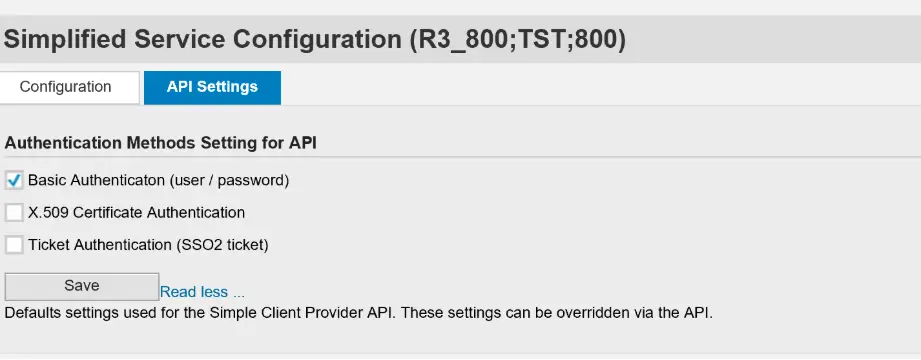
SAP’s web service authentication settings required careful tuning. Multiple configurations were tested before identifying the correct combination of HTTP handler and service user credentials that allowed external SOAP calls to succeed.
Date Filter Logic
Initial work-order retrieval returned data outside the requested date range. The ABAP selection logic was corrected to enforce strict date boundary matching (GSTRP GE i_start AND GSTRP LE i_end), and output dates were reformatted to DD/MM/YYYY.
Vendor Number Formatting
Vendor numbers required CONVERSION_EXIT_ALPHA_OUTPUT normalisation to strip leading zeros and match expected formats in the consuming application.
Compressed Timeline
All three phases were delivered in parallel with the client’s internal scheduling constraints, requiring iterative development with 2–3 day feedback cycles and daily stand-ups.
Key Benefits
- Reusable service layer — both SOAP and REST endpoints can be extended to additional SAP objects without re-architecture
- Zero middleware dependency — services are natively exposed from SAP, removing Informatica licensing requirements for the POC
- Rapid time-to-value — working, tested integration delivered in under 8 weeks from initial engagement
- Comprehensive documentation — WSDL definitions, ABAP code bundle, unit test evidence, and architecture notes handed over at project close
- Clean handover — 1-week hypercare period with all bugs resolved (100% test pass rate)
Post-Go-Live Support
Hypercare Period
A dedicated one-week hypercare period was included post-delivery. During this period DeepIQ resolved all outstanding defects, provided guidance on SAP navigation, and completed final documentation. All six functional test scenarios and both raised bugs were closed with a Pass status before handover.
Application screenshots are included below as placeholders — replace with actual Postman / SOAP UI test captures.
About Client
Electric Kiwi is an autonomous online New Zealand electricity retailer. Established in 2014, Electric Kiwi uses cloud computing and intelligent meters to service customers nationwide in major urban areas. Its services depend on the presence of the smart meters in the customer’s home. For the client, we did the POC for integrating AWS Support Services with Datadog’s CloudFormation template.
- http://www.electrickiwi.co.nz/
- Location: New Zealand
Project Background
The case study of the project provides a synopsis of how we did the POC for the client for integrating AWS Support Services, an AWS account with Datadog employing Datadog’s CloudFormation template. Creating an IAM role and associated policy enables Datadog’s AWS account to make API calls for collecting or pushing data into your AWS account. Using the CloudFormation template supplies all the tools required to send this data to your Datadog account, and Datadog helps the CloudFormation template to provide the latest functionality. The template even deploys the Datadog Forwarder Lambda operation for sending logs to Datadog.
After setting the initial connection, enable the individual AWS service integrations appropriate to your AWS domain. With a single click, Datadog provisions the required resources in your AWS account and starts analyzing the metrics and events for the services you use. For general AWS services you are using, Datadog needs out-of-the-box dashboards providing prompt and customizable visibility. The project background demonstrates setting up the integration and establishing the Datadog Agent on an Amazon Linux EC2 instance and feeds a broad outline of the integration’s capabilities. Visit the Enable integrations for individual AWS service factions for a list of the general sub-integrations.
This procedure can be repeated for multiple AWS accounts as required, or you can also use the API, AWS CLI, or Terraform to set up various accounts simultaneously. For more details, read the Datadog-Amazon CloudFormation guide.
Scope & Requirement
The scope & requirements involved the following:
- Datadog integration with AWS support services to measure and accomplish observability matrix
- Identified costing
- Updated pricing with partner discount as applicable
- Shortlisted services for which we did POC
- EC2, database Monitor Requirement, Steps, and Dashboard View
- Along with pricing and cost for using Datadog; for monitoring and analytical purpose
Implementation
Technology and Architecture
Technology/Services used
We used Datadog integration with AWS services to masure and do observability matrix and helped them to setup below
- Cloud: AWS
- Shortlisted services for which we did POC
- Organization setup: Control tower
- Policies setup: Created AWS service control policies
- Templates created for using common AWS services
Security & Compliance:
- Tagging Policies
- Azure config for compliance checks
- NIST compliance
- Guardrails
- Security Hub
Backup and Recovery
- AWS Backup provided a simple, secure, cost-effective, and cloud-based backup solution which was already implemented for the client
Network Architecture
- Site to Site VPN Architecture using Transit Gateway
- Distributed Azure Network Firewall
- Monitoring with Cloud Watch and VPC flow logs.
Cost Optimization
- Alerts and notifications are configured in the AWS cost
- Identified Costing
- Updated pricing with partner discount as applicable
Code Management, Deployment
- Cloudformation scripts for creating stacksets and scripts for generating AWS services was handed over to the client
Challenges
- Access was not provided to the actual environment and setting up
- Complex environment setup and monitoring for production cost was only possible to evaluate if we have got the access for the actual environment from the client
Support
- 1 month of extended support
- A template for Cloud formation stack to create more AWS resources using the available stacks
- Screen-sharing sessions with a demo of how the services and new workloads can be deployed.
About Client
Managing AWS Environment
Wine-Searcher is a web search engine that helps find the price and availability of any wine, whiskey, spirit, or beer worldwide. It has been in operation since 1999 and has offices in New Zealand and the UK. They provide an easy-to-use search engine, price comparison tools, an extensive database of wines and spirits, an encyclopedia, and news pages that aim to provide all “wine-finding” needs.
- https://www.wine-searcher.com/
- Location: New Zealand & UK
Project Background
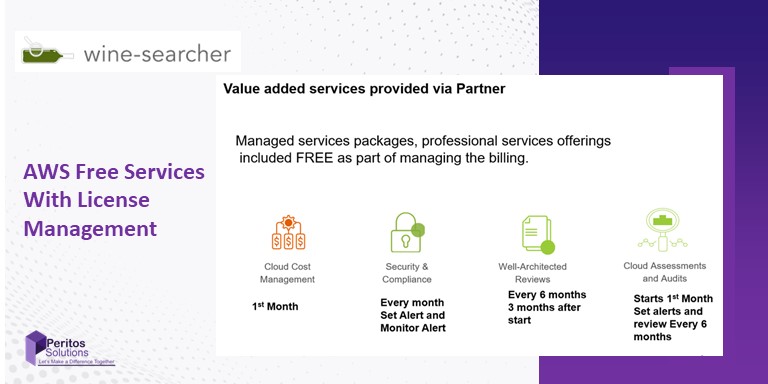
As part of their plan to launch a full suite of digital products, Wine-Searcher chose AWS as their cloud environment. Strategic resource allocation and cost optimization are critical to ensure a cost-effective operation. Peritos helped as the reliable AWS partner on AWS Cost Explorer and AWS Budgets, like valuable tools for implementing ongoing discounted billing. Furthermore, leveraging reserved instances and spot instances and optimizing usage based on peak hours and demand patterns can result in significant cost savings. Experts from the Peritos team helped regularly monitor and fine-tune the AWS environment based on Winesearcher’s needs, allowing for continuous optimization while adhering to budgetary constraints and maintaining the required scalability and performance for their operations.
Scope & Requirement for Managing AWS Environment
In the 1st Phase of the AWS Environment Setup, implementation was discussed as follows:
- Manage Billing
- Value added services
- Handling Complex environments
- Multiple AWS invoices
- Cost Optimization
- Cloud security optimization
Implementation
Technology and Architecture of Managing AWS Environment
Furthermore, Read on the key components that defined the Architecture for managing the AWS Environment Setup for Wine-Searcher
Technology/ Services used
We used AWS services and helped them to setup below
- Cloud: AWS
- Organization setup: Control tower
- AWS SSO for authentication using existing AzureAD credentials
- Policies setup: Created AWS service control policies
- Templates created for using common AWS services
Security & Compliance:
- Tagging Policies
- AWS config for compliance checks
- NIST compliance
- Guardrails
- Security Hub
Network Architecture
- Site to Site VPN Architecture using Transit Gateway
- Distributed AWS Network Firewall
- Monitoring with Cloud Watch and VPC flow logs.
Backup and Recovery
- Cloud systems and components used followed AWS’s well-architected framework, and the resources were all Multi-zone availability with uptime of 99.99% or more.
Cost Optimization
- Alerts and notifications are configured in the AWS cost
Code Management, Deployment
Cloudformation scripts for creating stack sets and scripts for generating AWS services were handed over to the client
Challenges in Implementing Managing AWS Environment
- Collate all accounts together
- Understand and agree on how the account would be managed under the distribution model
Support
- One month of extended support
- A template for Cloud formation stack to create more AWS resources using the available stacks
- Screen-sharing sessions with demos of how the services and new workloads can be deployed.
Next Phase
We are now looking at the next phase of the project, which involves:
- Implementing a control tower for the client.
About Client
AWS Environment Setup
Tonkin + Taylor is New Zealand’s leading environment and engineering consultancy with offices located globally. They shape interfaces between people and the environment which includes earth, water and air. They have won awards like Beaton Client Choice Award for Best Provider to Government and Community-2022 and IPWEA Award for Excellence in Water Projects for the Papakura Water Treatment Plan- 2021.
- https://www.tonkintaylor.co.nz/
- Location: New Zealand
Project Background
Tonkin + Taylor were embarking on the journey for launching a full suite of digital product and zeroed upon AWS as thier choice for cloud environment. They wanted to create new applications and migrate to cloud services to improve their scalability, ensure availability, minimize latency and reduce costs. They were also looking to accelerate their digital transformation and add greater business value through AWS Development Environment best practices. Lastly with the new apps they wanted to monetize and create SAAS based offerings for the end users. For all this it was needed to do AWS Environment Setup which follows best practices and meets compliance which can be used as a base for implementing more applications.
Scope & Requirement
In the 1st Phase of the AWS Environment Setup, implementation was discussed as follows:
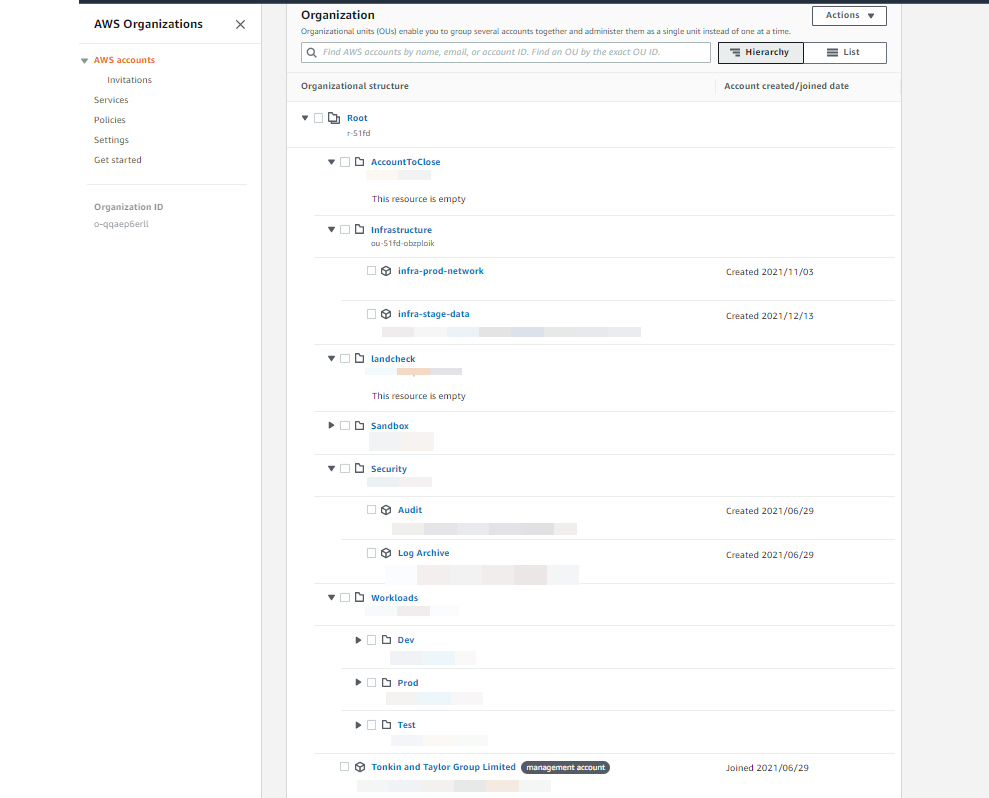
- Setting up AWS environment for multi account, Multi environment setup
- Ensure the all AWS accounts follow same set of policies and adhering to all legal and regulatory compliance.
- Setup connectivity between different AWS accounts and on-prem network
- Setup AWS security hub to provide a comprehensive view of security state
- The Tonkin + Taylor On-Premise to Cloud Migration project aims to modernize and optimize the company’s IT infrastructure by migrating its existing on-premise systems to a cloud-based environment. The key objectives include reducing operational costs, enhancing scalability, improving system performance, and ensuring business continuity through a secure, reliable, and accessible cloud platform.
Implementation
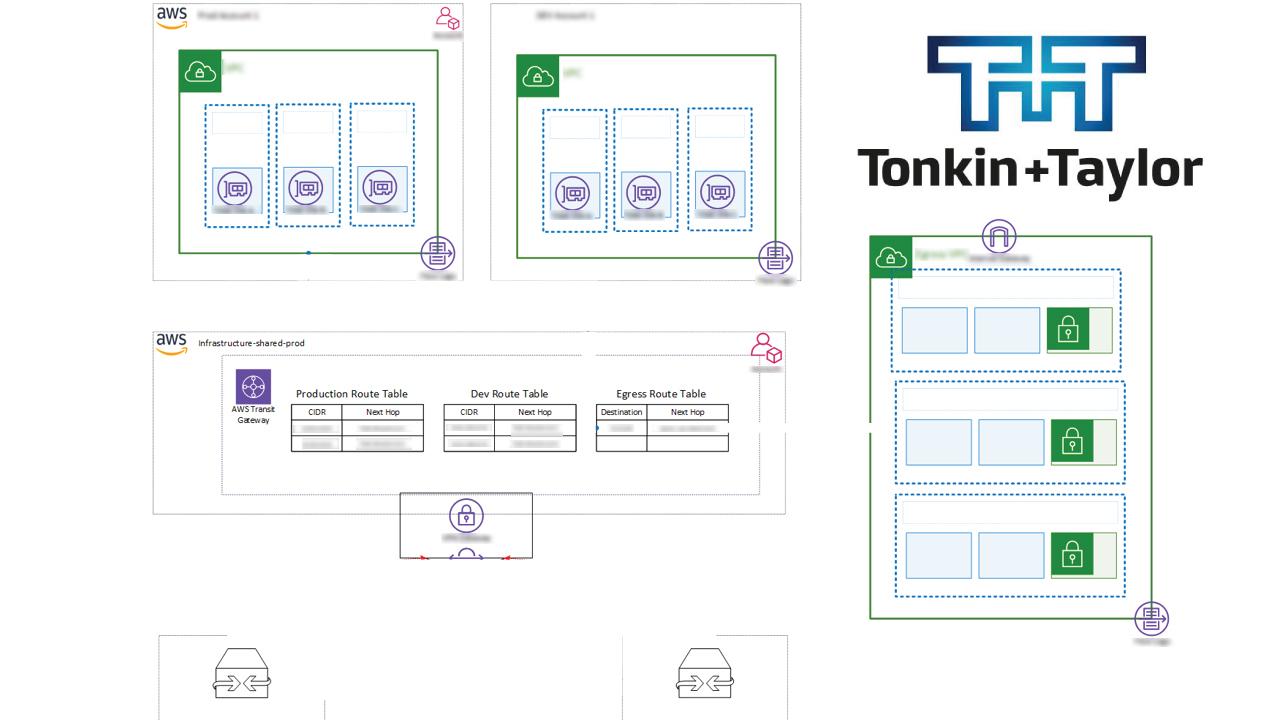
Technology and Architecture
Read more on the key components which defined the Architecture for AWS Environment Setup for Tonkin + Taylor
Technology/ Services used
- We used AWS services and helped them to setup below
- Cloud: AWS
- Organization setup: Control tower
- AWS SSO for authentication using existing AzureAD credentials
- Policies setup: Created AWS service control policies
- Templates created for using common AWS services
Security & Compliance:
- Tagging Policies
- AWS config for compliance checks
- NIST compliance
- Guardrails
- Security Hub
Network Architecture
- Site to Site VPN Architecture using Transit Gateway
- Distributed AWS Network Firewall
- Monitoring with Cloud Watch and VPC flow logs.
Backup and Recovery
Cloud systems and components used followed AWS’s well-Architected framework and the resources were all Multi-zone availability with uptime of 99.99% or more.
Cost Optimization
Alerts and notifications are configured in the AWS cost
Code Management, Deployment
Cloudformation scripts for creating stacksets and scripts for generating AWS services was handed over to the client
Challenges of AWS Environment Setup
- It was a bit of a challenge to ensure the new environment meets all of the compliance criteria and still remain cost effective.
- As per best practices we need to have a set of Unique machines and each may need to have its own VPC but that may incur a cost to the client. So we discussed and agreed for a specific 75% to be achieved which would be deemed as acceptable
- We have some non compliance being generated by standard AWS services
- We got below feedback from AWS support . “It was reported that there are some policies and roles which are created by control tower and are created using best practices and there is no harm or security issue which arises it. Sometimes the conformance pack you use does shows the by default created policies to be non-compliant and you can ignore that for the time being. To make it compliant we have to either delete or the modify these roles/policies and since these roles and policies managed by the Control Tower, it is recommended not to manually update/delete the roles attached. Diving deeper into the issue, I could refer that the Control Tower managed artifacts feature heavily on the compliance failure list and there is no way to specifically exclude Control Tower managed artifacts from the compliance checking. Checking further with the internal team, I found that they are aware of the issue and there has been an ongoing feature request to exclude Control Tower managed artifacts from the compliance checking to avoid these such security findings. ” So based on this feedback we ensured to make a note that the non compliance being shown may not be an accurate one and these would be treated as exceptions.
Support
- 1 month extended support
- A template for Cloud formation stack to create more AWS resources using the available stacks
- Screen sharing sessions with demo of how the services and new workloads can be deployed.
- Offer support during the initial transition phase post-migration.
- Provide ongoing technical support, monitoring, and optimization services.
Next Phase
We are now looking at the next phase of the project which involves:
- Launching new digital products with the help of AWS environments which have been setup
- Any adhoc change requests for managing the cloud environment
About Client
AWS Control Tower Setup
Wine-Searcher is a web search engine that helps find the price and availability of wine, whiskey, spirits, and beer worldwide.
It has been operating since 1999, with offices in New Zealand and the UK. The platform offers search tools, price comparison,
an extensive database, an encyclopedia, and news content to support all wine-finding needs.
- https://www.wine-searcher.com/
- Location: New Zealand & UK
Project Background
Peritos led the AWS Control Tower setup for Wine-Searcher, optimizing their cloud infrastructure.
The implementation streamlined governance, improved compliance, and enabled secure scalability.
Multiple accounts were consolidated and managed using AWS Organizations within Control Tower.
The environment was configured to meet specific business needs, ensuring efficient resource management
and cost control. With built-in automation and governance, Wine-Searcher gained a strong foundation
for future growth while focusing on innovation and user experience.
Scope & Requirement for AWS Control Tower Setup
- Prerequisite: Automated pre-launch checks for the management account
- Step 1: Create shared account email addresses
- Define expectations for landing zone configuration
- Step 2: Configure and launch the landing zone
- Step 3: Review and finalize the landing zone setup
Implementation
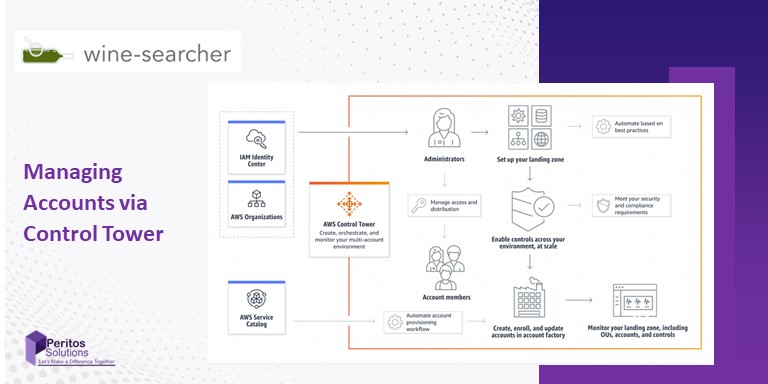
Technology and Architecture of AWS Control Tower Setup
- Read about the key components defining the AWS Control Tower architecture for Wine-Searcher
Technology / Services Used
- We used AWS services to set up the following:
- Cloud: AWS
- Organization setup: Control Tower
- AWS SSO integrated with Azure AD credentials
- Policies setup: AWS Service Control Policies (SCPs)
- Templates created for common AWS services
Security & Compliance
- Tagging policies
- AWS Config for compliance checks
- NIST compliance
- Guardrails
- Security Hub
Network Architecture
- Site-to-site VPN using Transit Gateway
- Distributed AWS Network Firewall
- Monitoring with CloudWatch and VPC Flow Logs
Backup and Recovery
- Infrastructure follows AWS Well-Architected Framework with multi-zone availability and 99.99% uptime
Cost Optimization
Alerts and notifications are configured to monitor AWS costs and prevent budget overruns.
Code Management & Deployment
CloudFormation scripts for stack sets and AWS service provisioning were handed over to the client.
Challenges in Implementing AWS Control Tower Setup
- Landing Zone Drift
- Role Drift
- Security Hub Control Drift
- Trusted Access disabled
Support
- 1 month extended support
- A template for Cloud formation stack to create more AWS resources using the available stacks
- In addition, Screen sharing sessions with demo of how the services and new workloads can be deployed.
Executive Summary
The Tellabs AWS Glue integration project was designed to establish a secure, scalable, and automated data integration pipeline between Oracle NetSuite and AWS. Leveraging AWS Glue, Amazon S3, and orchestration services such as Step Functions and EventBridge, the solution ensures efficient data extraction, transformation, and storage. The Objective was to build and implement automated ETL pipelines to ensure key reporting metrics are improved in terms of speed and accuracy.
A strong emphasis was placed on security, governance, monitoring, and automation, ensuring that all workloads align with AWS best practices. The implementation provides enhanced visibility, operational resilience, and cost optimization for data processing workflows.
About Client
Tellabs is a technology-driven organization requiring secure and scalable cloud infrastructure to support its data integration and analytics workloads. The customer needed a robust AWS-based solution to handle data ingestion from Oracle NetSuite while maintaining strict governance, security, and compliance standards.
Objectives
- Establish a secure AWS account governance model
- Enable seamless integration with Oracle NetSuite
- Implement automated ETL pipelines using AWS Glue
- Ensure high availability and performance monitoring
- Maintain secure access control and identity management
- Enable cost visibility and optimization for Glue jobs
Scope of Engagement
- AWS Account Setup & Governance
- Identity & Access Management (IAM / SSO)
- AWS Glue ETL Pipeline Development
- Monitoring & Logging Framework
- Network Security Implementation (VPC, SG, NACL)
- Deployment Automation using CloudFormation
- Cost Analysis & Optimization
- Runbook Creation & Operational Support
Architecture Overview
The architecture consists of:
- Source System: Oracle NetSuite
- Processing Layer: AWS Glue
- Storage Layer: Amazon S3
- Orchestration: AWS Step Functions & EventBridge
- Secrets Management: AWS Secrets Manager
- Monitoring: Amazon CloudWatch & CloudTrail
This architecture ensures scalability, automation, and secure data processing pipelines.
Solution Overview – To implement automated ETL pipelines using AWS Glue
The solution integrates Oracle NetSuite with AWS using Glue-based ETL pipelines. Data is extracted, transformed, and stored in S3, enabling downstream analytics and reporting.
Key capabilities:
- Automated ETL workflows
- Event-driven execution using EventBridge
- Secure credential handling via Secrets Manager
- Centralized logging and monitoring
- Scalable serverless architecture
Security & Governance
AWS Account Governance SOP
- Root account restricted to initial setup only
- Mandatory MFA enabled on root account
- Use of corporate email & contact details
- CloudTrail enabled across all regions
- Logs stored in secure S3 bucket with deletion protection
Identity & Access Management
- Principle of Least Privilege
- Use of IAM roles & temporary credentials
- Integration with AWS SSO / Active Directory
- No wildcard permissions in policies
- Individual access accountability
Network Security (VPC)
- Security Groups for controlled traffic
- Subnet-level control via Network ACLs
- Restricted DB access to application layer only
- Controlled internet access pathways
Data Security
- Encryption using AWS KMS CMKs
- SSL/TLS for data in transit
- Key rotation enabled
- Fine-grained access control policies
Implement automated ETL pipelines using AWS Glue and ensure to manage Security and Access control
Monitoring & Logging
- CloudWatch Dashboards for:
- Glue job performance
- Step Functions execution
- EventBridge events
- CloudTrail for audit logging
- Logs exported to Amazon S3
- SNS alerts for:
- Job failures
- Latency spikes
- Credential access issues
Implement automated ETL pipelines using AWS Glue and ensure monitoring and Observability by automating data pipelines
Implementation
Infrastructure as Code
- AWS CloudFormation used for:
- Infrastructure provisioning
- Security configurations
- Networking setup
CI/CD Automation
- Integrated with AWS CodeBuild
- Automated deployment pipeline
- No manual console changes
Glue Implementation – automated ETL pipelines using AWS Glue
- ETL jobs configured with optimized DPUs
- Logging enabled for all executions
- Job performance tracked via CloudWatch
Runbook & Troubleshooting
Routine Monitoring Tasks
- Monitor AWS Lambda execution metrics
- Check API Gateway latency & security logs
- Review Aurora DB performance metrics
Troubleshooting Scenarios
Lambda Errors
- Analyze CloudWatch logs
- Adjust timeouts/configurations
API Gateway Latency
- Identify backend bottlenecks
- Optimize integrations
Aurora DB Issues
- Optimize queries & indexing
- Resolve connection bottlenecks
High Latency Scenario (OPE-001)
- Trigger incident response
- Identify root cause
- Apply performance optimizations
Deployment Readiness Checklist
Testing
- Unit Testing
- Integration Testing
- System Testing
- User Acceptance Testing (UAT)
Automation
- CI/CD pipelines
- Automated testing frameworks
- Security & code quality scans
Documentation
- Deployment guide
- Rollback strategy
- Configuration records
Validation
- Pre & post deployment checks
- Deployment checklist completion
- Evidence of successful rollout
Cost Optimization & Performance Tuning for running and implementing automated ETL pipelines using AWS Glue
- Glue pricing based on DPU usage & runtime
- Cost analysis using:
- CloudWatch logs
- AWS Cost Explorer
- Optimization strategies:
- Reduce over-allocated DPUs
- Use Glue Python shell jobs for smaller workloads
- Enable job bookmarks to avoid reprocessing
- Automation via:
- boto3 scripts
- Athena-based reporting
Challenges & Resolutions
| Challenge | Resolution |
| Secure access management | Implemented IAM roles & SSO |
| Monitoring complexity | Centralized CloudWatch dashboards |
| Cost visibility | Implemented tagging & cost analysis |
| Data security compliance | Used KMS CMKs & encryption |
| Deployment consistency | Adopted CloudFormation IaC |
Project Completion
- Successfully deployed automated ETL pipelines
- Established secure AWS governance model
- Enabled real-time monitoring and alerting
- Improved performance and reduced operational risks
- Delivered scalable and maintainable architecture
Note
This implementation follows AWS best practices for:
- Security
- Reliability
- Performance Efficiency
- Cost Optimization
- Operational Excellence
Implement automated ETL pipelines using AWS Glue high-level system setup.
Reference Links
https://docs.aws.amazon.com/prescriptive-guidance/latest/patterns/build-an-etl-service-pipeline-to-load-data-incrementally-from-amazon-s3-to-amazon-redshift-using-aws-glue.html
Read more about Glue
https://aws.amazon.com/glue/
Read more here about our services
AWS Glue Services
- https://www.peritossolutions.com/services/aws-glue-serverless-data-integration/
AWS consulting Services
- https://www.peritossolutions.com/aws-consulting
About Client
1Place is a technology-driven organization focused on leveraging data to enhance decision-making, reporting, and operational intelligence. The company manages a growing data ecosystem comprising multiple data sources, analytics tools, and business applications. AWS offers glue as a fully managed etl service
To address scalability challenges and improve data automation, 1Place collaborated with Peritos Solutions, an AWS Advanced Consulting Partner, to design and implement a serverless data platform using AWS Glue. The goal was to replace manual data workflows with a secure, automated ETL framework that ensures accuracy, consistency, and governance.
Project Background – Data Modernization through AWS Glue ETL service
1Place data operations were previously dependent on traditional ETL tools that lacked automation and flexibility. These manual processes caused data silos, inconsistent data quality, and delayed reporting.
Peritos Solutions proposed an AWS Glue-based serverless ETL framework to transform 1Place data landscape. The solution automated schema detection, data cataloging, and transformation pipelines while ensuring end-to-end visibility through AWS CloudWatch and centralized governance.
This transformation allowed 1Place to manage large-scale data workloads with minimal operational overhead while maintaining compliance, traceability, and cost efficiency.
Objectives of the Engagement
- Establish a serverless, automated data integration framework using AWS Glue ETL service
- Replace legacy ETL pipelines with scalable and efficient Glue jobs
- Implement centralized metadata management using AWS Glue Data Catalog.
- Enable cross-service data integration with S3, RDS, and Redshift.
- Ensure security, governance, and compliance through IAM, encryption, and monitoring.
Scope & Requirements
Scope
The project’s scope included the design, deployment, and optimization of AWS Glue components to enable seamless data flow across 1Place AWS environment.
Key deliverables included:
- AWS Glue Crawlers for automated schema detection.
- Glue Jobs for data transformation and enrichment.
- Glue Workflows for end-to-end orchestration.
- Centralized Data Catalog for metadata governance.
- CloudWatch monitoring and alerting integration.
Requirements
Functional:
- Automated ETL pipeline creation and scheduling.
- Dynamic schema detection and updates.
- Integration with Amazon Redshift and Athena for analytics.Non-Functional:
- Serverless architecture for scalability.
- Secure access control with IAM.
- Centralized monitoring and auditing.
- Cost efficiency and fault tolerance.
AWS Glue ETL service Implementation support for Pipeline Automation
Solution Overview -AWS Glue ETL service
Business Problem Addressed
1Place existing ETL infrastructure was time-intensive and not scalable. Manual intervention led to delays, higher costs, and inconsistent data quality.
Proposed AWS Glue-Based Solution
Peritos Solutions implemented an end-to-end AWS Glue solution integrating multiple data sources and automating data transformation and cataloging. Using Glue Crawlers, Jobs, and Workflows, the entire ETL process became event-driven, reducing human intervention and operational latency.
Key Benefits
- Serverless data integration with zero infrastructure management.
- Automated data discovery and schema management.
- Faster and more reliable data transformation pipelines.
- Improved data governance through centralized metadata.
- Seamless analytics enablement through Athena and QuickSight integration.
Implementation -AWS Glue ETL service
Architecture Overview
The architecture consisted of:
- Data Sources: S3, RDS, and on-premises data via secure connectors.
- ETL Layer: AWS Glue Crawlers, Jobs, and Workflows.
- Data Catalog: Centralized schema and metadata management.
- Analytics Layer: Athena and QuickSight for visualization.
- Monitoring & Logging: CloudWatch for logs, metrics, and alerts.
Technology Stack
- AWS Services: Glue, S3, RDS, Redshift, CloudWatch, Lambda, Secrets Manager, IAM.
- Security: KMS encryption, MFA-enabled IAM roles, and cross-account logging.
- Automation: CI/CD pipelines with AWS CodePipeline and CodeBuild.
AWS Glue Components Implemented
- Glue Crawlers: Automated schema discovery for S3 and RDS datasets.
- Glue Jobs: ETL scripts built using PySpark to clean, normalize, and enrich data.
- Glue Workflows: Orchestration for dependency-based execution.
- Data Catalog: Managed metadata, table schemas, and data lineage.
- Triggers: Event-driven execution using CloudWatch and EventBridge.
Security and Compliance
- IAM policies applied with least privilege.
- Glue roles restricted to authorized services only.
- KMS encryption applied for data at rest and in transit.
- CloudTrail enabled for audit trails and compliance verification.
Runbook and Troubleshooting Scenarios
Routine Operational Tasks
- Daily monitoring of Glue job metrics and DPU utilization.
- Reviewing failed job logs and rerunning based on SLA thresholds.
- Verifying Data Catalog updates and schema integrity.
- Checking Glue job triggers and workflow dependencies.
Common Troubleshooting Scenarios
- Job Failures Due to Schema Drift: Re-run Glue Crawler, refresh Data Catalog, and update ETL script mapping.
- Performance Degradation: Tune Spark configurations and increase DPU allocation.
- Connection Errors: Validate IAM permissions, VPC configurations, and network paths.
- Data Quality Issues: Use Glue dynamic frames and AWS Deequ for validation.
AWS Glue ETL service Implementation support
Deployment Readiness Checklist
Testing
- Unit, integration, and system testing of all Glue jobs.
- Validation of schema mapping, data accuracy, and job success rates.
Automation
- CI/CD pipelines integrated for job versioning and automated deployment.
- Security scans embedded in build pipelines.
Documentation
- Deployment runbook, rollback plan, and configuration details maintained.
Monitoring & Validation
- Glue job metrics and alerts verified in CloudWatch.
- Post-deployment validation ensured job stability.
Evidence: Deployment logs, Glue job screenshots, and automation reports attached to project documentation.
Cost Optimization and Performance Tuning
- Used Glue 3.0 for faster job performance and improved scaling.
- Optimized DPU allocation and job parallelism.
- Leveraged job bookmarks for incremental data loads.
- Enabled data partitioning in S3 for query efficiency.
- Monitored spend through AWS Cost Explorer and adjusted scheduling.
Challenges and Resolutions
| Challenge | Resolution |
| Schema evolution from multiple data sources | Automated schema updates via Glue Crawlers |
| Long-running ETL jobs | Spark job optimization and dynamic partitioning |
| Data duplication in catalogs | Automated Data Catalog cleanup and versioning |
| Integration with legacy databases | Implemented secure JDBC connections and Glue connections |
| Monitoring job failures | Integrated CloudWatch alerts with email/SNS notifications |
Project Completion – AWS Glue ETL service
Deliverables
- AWS Glue Data Catalog, Crawlers, Jobs, and Workflows.
- CloudWatch dashboards for Glue performance monitoring.
- Operational Runbook and Troubleshooting Guide.
- Deployment Readiness Checklist and Evidence Reports.
- CI/CD pipelines for Glue job automation.
Support
Post-implementation support for two months, including 20 hours/month of operational support, bug fixes, and performance optimization.
Next Phase
- Integrate with AWS Lake Formation for enhanced data governance.
- Implement data lineage tracking and metadata versioning.
- Expand to real-time streaming ETL using AWS Glue and Kinesis.
- Develop monitoring dashboards using QuickSight for Glue job analytics.
- Conduct quarterly optimization reviews for cost and performance improvements.
AWS Glue ETL service Implementation support
Reference Links AWS Glue ETL service
https://docs.aws.amazon.com/prescriptive-guidance/latest/patterns/build-an-etl-service-pipeline-to-load-data-incrementally-from-amazon-s3-to-amazon-redshift-using-aws-glue.html
Read more about Glue
https://aws.amazon.com/glue/
Read more here about our services
AWS Glue Services
- https://www.peritossolutions.com/services/aws-glue-serverless-data-integration/
AWS consulting Services
- https://www.peritossolutions.com/aws-consulting


